// guides · 99 articles
Guides
Original, hands on guides from the TrueIQ editors: comparisons, “best tool for the job” roundups and plain English explainers.
Explainers · 8 min readListen
Agent Arena Index: How Arena Ranks AI Agents
The Agent Arena Index explained: the four signals behind Arena's agent leaderboard, how the score is weighted and anchored, and how to read the November 2026 board.
Explainers · 10 min readListen
Gemini 4 Neon Benchmarks: Which Claims Hold Up
Gemini 4 Neon benchmarks checked against Artificial Analysis, Vals, Arena, Terminal-Bench, Zapier and Cognition boards: which launch claims match and which do not.
Comparisons · 10 min readListen
Helicone vs LangSmith: Proxy Logs or Agent Traces?
Helicone vs LangSmith in 2026: request logs and a mature gateway against agent traces, evals and a new beta gateway. What each bills, sees and costs, tested.
Leaderboards · 9 min readListen
SO-Arena Benchmark: How System One Models Rank
SO-Arena tests System One decision models on 2,919 tasks in 11 domains. Who leads, why the top scorer is only seventh on reliability, and how to read it.
Comparisons · 9 min readListen
HoneyHive vs Langfuse: Free Tiers, Evals and Hosting
HoneyHive vs Langfuse in 2026: what each one bills as an event, free tier math from a real SDK test, evals, self hosting and which team should pick which.
Comparisons · 9 min readListen
GPTZero vs QuillBot: Which Catches Paraphrased AI?
GPTZero vs QuillBot in 2026: free limits, prices, our read of both RAID result files, and which detector caught QuillBot paraphrased AI text in outside tests.
Comparisons · 9 min readListen
GPTZero vs ZeroGPT: Which AI Detector to Trust?
GPTZero vs ZeroGPT in 2026: who makes each, free limits, prices, and what RAID and four independent studies found about false flags on real human writing.
Explainers · 9 min readListen
Gemini 4 Hydrogen Benchmarks: What Holds Up
Gemini 4 Hydrogen benchmarks checked against Artificial Analysis, Vals, Terminal-Bench, Snorkel and Arena boards: which launch scores hold up and which do not.
Comparisons · 10 min readListen
ARC-AGI vs Humanity's Last Exam: Key Differences
ARC-AGI vs Humanity's Last Exam: one tests how fast a model learns a new puzzle, the other tests expert knowledge. Scores, grading, cost and which to trust.
Explainers · 10 min readListen
Langfuse AI Gateway: What It Logs and Costs
Langfuse AI Gateway routes OpenAI and Anthropic calls through Langfuse and traces each one. What it records, what it costs, its beta limits and who it suits.
· updated
How to · 10 min readListen
How to Use GPTZero in Google Docs (2026)
How to use GPTZero in Google Docs: install the free extension, scan from the GPTZero menu, highlight AI sentences and open a shareable Writing Report.
Comparisons · 10 min readListen
Helicone vs Langfuse: Which to Pick in 2026
Helicone vs Langfuse in 2026: a proxy first logger in maintenance mode against an actively built tracing and eval platform. Pricing, gateways and when to move.
Leaderboards · 10 min readListen
Jev Decision Index: How Decision Models Rank
The Jev Decision Index ranks 275 decision models on private tests. How the Full score works, who leads, why Jev sits 55th, and how it differs from AA's index.
Explainers · 8 min readListen
How Much Is Gradescope? Real Prices in 2026
How much is Gradescope? Basic is free, Institutional is quote only, and public contracts show what universities really pay, from $4 a student to $231,525.
Comparisons · 10 min readListen
Prompt Injection Detection Library: What to Use
Which prompt injection detection library to use in 2026: Llama Prompt Guard 2, Protect AI DeBERTa, Pytector, rule scanners and APIs, with our own 12 prompt test.
Comparisons · 10 min readListen
Pangram vs Copyleaks: Which AI Detector Wins?
Pangram vs Copyleaks in 2026: price per 1,000 words, free limits, plagiarism, LMS plugins, and what the 2023 and 2026 studies found when each detector was tested.
Leaderboards · 9 min readListen
Harness Leaderboard: How the Harness Moves Scores
The Harness Leaderboard runs 9 coding agent harnesses on the same open models. What v0.1.3 shows, who ties for first, what it costs, and the caveats.
Explainers · 10 min readListen
LLM Judge Model: Frontier, Small or Decision Model?
Which LLM judge model should grade your outputs? Frontier LLMs, small judges and decision models like Jev compared on accuracy, cost and calibration.
· updated
Comparisons · 10 min readListen
Pangram vs Winston AI: Which Should You Use?
Pangram vs Winston AI in 2026: free limits, prices per word, plagiarism, languages, and what RAID and the Chicago Booth tests really show about each detector.
Comparisons · 9 min readListen
LLM as a Judge vs Agent as a Judge: When to Switch
LLM as a judge vs agent as a judge: what each grades, what DevAI, AJ-Bench and Mind2Web 2 found, what an agent judge costs, and when to switch.
Explainers · 10 min readListen
VIALS-AA: What Scientific Image Scores Mean
VIALS-AA is Artificial Analysis's independent board for Handshake AI's 161 task scientific image test. How pass cubed works, what scores show, and the limits.
Explainers · 10 min readListen
Patronus AI Agent Failure Research, Explained
Patronus AI agent failure research in plain English: what the 63% figure really means, what the TRAIL benchmark found and how to find failures in your own agents.
Comparisons · 9 min readListen
OpenLLMetry vs Langfuse: Instrumentation or Platform?
OpenLLMetry vs Langfuse in 2026: one captures LLM traces, the other stores and scores them. See how they fit together, what each costs and when to pick which.
How to · 9 min readListen
How to Spot AI Scam Ads on Facebook and YouTube
How to spot AI scam ads that use deepfake celebrities on Facebook, Instagram and YouTube: the red flags, a quick check, how to report them and what detectors miss.
Explainers · 10 min readListen
Which LLM Benchmark Measures Tool Calling?
Which LLM benchmark measures tool calling? BFCL V4 is the public standard for function calls; Tau bench and ToolBench cover dialogue and large API inventories.
· updated
Explainers · 9 min readListen
Pangram Image 1.0: Models, Scores and Limits
Pangram Image 1.0 and Flash 1.0 for AI images and video: heatmaps, DF26 claims, free scan limits, API rates, and when Hive or SynthID is a better fit.
How to · 9 min readListen
How to Evaluate LLMs Before Production
How to evaluate LLMs before production: set the product decision, build a production like offline suite, wire CI gates, then open shadow or A/B traffic.
Explainers · 8 min readListen
Terminal-Bench Explained: 4.0, 4.1, Scores
Terminal-Bench explained: how the 66 task agent shell benchmark works, what changed in 4.0 and 4.1, and how to read official, Vals and Artificial Analysis scores.
· updated
Comparisons · 9 min readListen
Originality.ai vs Pangram: Which Should You Use?
Originality.ai vs Pangram in 2026: free limits, prices, Epoch AI accuracy numbers, mixed writing claims, and which detector fits publishers or reviewers.
Explainers · 8 min readListen
Is Pangram Labs Free? Plans and Limits (2026)
Is Pangram Labs free? Yes for light use: 2,000 words a day, no card. Free limits, Individual and Professional prices, API credits and when to upgrade.
Comparisons · 8 min readListen
Ragas vs Langfuse for RAG Evaluation (2026)
Ragas vs Langfuse is a metrics library versus an open source tracing platform. How scores attach to traces, when to use both, pricing, and a tested wiring note.
· updated
How to · 9 min readListen
How to Use the PyRIT Tool: A Tested Walkthrough
How to use the PyRIT tool from Microsoft: install it, configure a target, run your first attack with converters and a scorer, then try the scanner and Crescendo.
Explainers · 9 min readListen
Grok Text Watermark: What Changes on November 7
Does Grok watermark text? From Nov 7, 2026, Grok API text from seven models carries an invisible watermark by default. How it works, how to check it and opt out.
Comparisons · 10 min readListen
Ragas vs LangSmith for RAG Evaluation (2026)
Ragas vs LangSmith: a free metrics library versus a paid eval platform. What each scores, what it costs, a tested way to run Ragas inside LangSmith, and Ragas risks.
· updated
Explainers · 10 min readListen
Is Reality Defender Free? Plans and Limits (2026)
Is Reality Defender free? Yes, for developers: 50 API scans a month, images and audio only. What the free plan covers, what Business costs and the extension catch.
Explainers · 9 min readListen
GDPx Benchmark Explained: Tasks, Scores, Limits
The GDPx benchmark from SemiAnalysis tests AI agents on 206 hard tasks in 11 domains. How it is scored, what the first results show, and where it misleads.
Explainers · 10 min readListen
LLM Evaluation for A/B Testing: How to Run It
LLM evaluation for A/B testing explained: when offline evals stop being enough, what live metrics to log, how big the test must be, and traps that skew results.
· updated
How to · 10 min readListen
How to Use Promptfoo: A Tested Walkthrough
How to use Promptfoo, step by step: install it, write a promptfooconfig.yaml, add assertions, compare two versions, read results and gate CI on the pass rate.
· updated
How to · 10 min readListen
How to Check If a Video Is AI Generated (2026)
How to check if a video is AI generated in 2026: platform labels, Content Credentials, SynthID Detector, classifiers and the source checks that still matter.
· updated
Explainers · 10 min readListen
RAG Evaluation Through Python: A Tested Walkthrough
RAG evaluation through Python, tested: score retrieval with plain Python hit rate, recall and MRR, add Ragas 0.4 metrics, and see which answer scores mislead.
· updated
Explainers · 10 min readListen
Open LLM Leaderboard v2: How to Use It in 2026
Open LLM Leaderboard v2 explained: its six benchmarks, how normalized scores work, why Hugging Face retired it, and how to query or rerun it today.
Explainers · 10 min readListen
Fireworks Specialized Intelligence Index Explained
The Fireworks Specialized Intelligence Index tracks 66 real work AI benchmarks in 14 domains. How it scores models, what changed on Oct 28, and how to read it.
Explainers · 10 min readListen
Artificial Analysis Intelligence Index v5 Explained
Artificial Analysis Intelligence Index v5: the nine evaluations, new 25% weights, what was dropped, why old scores no longer compare, and how to read a v5 score.
· updated
Comparisons · 10 min readListen
TestGorilla vs HackerRank: Which Hiring Test Fits?
TestGorilla vs HackerRank: what each one actually tests, current prices, cost per candidate, AI and cheating rules, and which fits your hiring in 2026.
Explainers · 10 min readListen
Are Brain Training Apps Effective? The Evidence
Are brain training apps effective? You get better at the games, but studies find little transfer to daily life. What the FTC, ACTIVE trial and meta analyses show.
Explainers · 10 min readListen
What Is Answer Completeness in RAG Evaluation?
What is answer completeness in RAG evaluation? The share of key facts from a reference answer that a response covers, and how Azure, Bedrock and Ragas score it.
How to · 10 min readListen
How to Use LangSmith with LangGraph (2026)
How to use LangSmith with LangGraph: set four environment variables, read node traces and threads, then score your graph and single nodes on a dataset.
Comparisons · 10 min readListen
Inspect AI vs DeepEval: Which Should You Use?
Inspect AI vs DeepEval in 2026: how the two open source eval frameworks differ on who runs the model, scoring, agents, sandboxes, CI and which team each one suits.
· updated
Comparisons · 10 min readListen
LiveBench vs Artificial Analysis: Key Differences
LiveBench vs Artificial Analysis: how the two AI leaderboards differ on tasks, grading, weighting and cost, why their rankings disagree, and when to trust each.
· updated
Explainers · 10 min readListen
What Is Claudish? Why AI Text Is Hard to Read
What is Claudish? The dense style of AI coding agents, what a new study found about why AI text is hard to read, and what it means for spotting AI writing.
Explainers · 9 min readListen
Is LangSmith API Free? Keys, Limits and Costs
Is LangSmith API free? Yes: API keys and the REST API cost nothing, and the Developer plan covers 5,000 traces a month. See key types, limits and overage costs.
Leaderboards · 10 min readListen
Coding Agent Benchmark Rankings (October 2026)
Coding agent benchmark rankings from SWE-Bench Pro, FrontierCode, Terminal-Bench and the Artificial Analysis index, with sourced scores, dates and why they differ.
· updated
Explainers · 10 min readListen
Is Langfuse Free for Commercial Use? (2026)
Is Langfuse free for commercial use? Yes: the MIT core can be self hosted in paid products at no cost. See what needs a license key and when the cloud bills.
· updated
Explainers · 10 min readListen
FrontierCode Benchmark Explained: How It Scores
The FrontierCode benchmark explained: how Cognition grades whether maintainers would merge AI code, what Main and Diamond mean, and how to read the leaderboards.
· updated
How to · 9 min readListen
How to Use the MMLU Benchmark, Step by Step
How to use MMLU benchmark runs: pick the right variant, run it with lm-evaluation-harness or Inspect, smoke test the format, and read the score honestly.
Explainers · 6 min readListen
How Does Turnitin Detect AI? What the Score Means
How does Turnitin detect AI? It scores overlapping prose segments by sentence. What it skips, why 1 to 19 percent shows an asterisk, and what to do if flagged.
How to · 10 min readListen
How to Detect AI Writing: A Step by Step Guide
How to detect AI writing: read for the patterns, check facts and sources, run two detectors, ask for drafts, then talk to the writer. A careful method, free.
Comparisons · 9 min readListen
Datadog LLM Observability vs Langfuse (2026)
Datadog LLM Observability vs Langfuse: how each bills (LLM spans vs units), retention, self hosting, evals and setup, with worked cost examples for 2026.
Explainers · 9 min readListen
Artificial Hivemind: Why AI Models Sound Alike
The Artificial Hivemind paper explained: why AI models give the same answers, what Infinity-Chat and NoveltyBench measure, and how to test output diversity yourself.
Comparisons · 10 min readListen
Originality.ai vs GPTZero: Which Should You Use?
Originality.ai vs GPTZero in 2026: free limits, prices, what the Epoch AI test found on human and AI text, and which detector fits publishers or teachers.
Comparisons · 10 min readListen
MMLU vs GPQA: Key Differences and Which to Use
MMLU vs GPQA explained: broad exam recall versus expert written science questions, why GPQA scores run lower, and which benchmark still means anything in 2026.
Explainers · 9 min readListen
LLM Confidence Scores: Can You Trust Them?
Can you trust an LLM confidence score? What verbalized scores, logprobs and sampling measure, what 2026 calibration research shows, and how to set safe thresholds.
Explainers · 9 min readListen
What Is Faithfulness in RAG Evaluation?
What is faithfulness in RAG evaluation? The share of an answer's claims backed by the retrieved context, and how Ragas, DeepEval, TruLens and HHEM score it.
Explainers · 7 min readListen
RAID Benchmark: How to Read the AI Detector Board
The RAID benchmark tests AI text detectors on 6 million samples with attacks. What it measures, how to read the leaderboard, and why 99 percent scores mislead.
How to · 9 min readListen
How to Take a Coding Test: Step by Step
How to take a coding test: check your setup, read every task, submit a correct solution early, then test edge cases and speed, using HackerRank and Codility rules.
Explainers · 10 min readListen
GDPval Benchmark: 1,320 Real Work Tasks, 44 Jobs
GDPval is OpenAI's AI test of 1,320 real work tasks from 44 occupations. How grading works, how to read the GDPval-AA board, and what it misses.
· updated
Explainers · 10 min readListen
ChatGPT Watermark: How OpenAI's textGrain Works
Does ChatGPT have a watermark? In the EU, yes: OpenAI's textGrain hides a pattern in word choices. How it works, who can detect it, and what it can't prove.
· updated
How to · 9 min readListen
How to Evaluate LLM Model Performance
How to evaluate LLM model performance before you pick one: build a task test set, fix settings, add error bars, test prompt sensitivity, then weigh cost.
· updated
Comparisons · 7 min readListen
MMLU vs SWE-bench: Which Should You Use?
MMLU vs SWE-bench explained: what each measures, why the scores are not comparable, and which benchmark to trust for knowledge vs coding agents in 2026.
Comparisons · 9 min readListen
MMLU vs MMLU Pro: Key Differences and Which to Use
MMLU vs MMLU Pro explained: how the 4 option and 10 option benchmarks differ, why their scores aren't comparable, and which one to trust for LLMs in 2026.
· updated
Explainers · 10 min readListen
What Is AI Detection? A Plain English Guide
What is AI detection? A plain English guide to how AI detection software works, what an AI detection report shows, its limits and Google Classroom options.
· updated
Explainers · 7 min readListen
AI Model Fingerprinting Explained
AI model fingerprinting embeds ownership signals in LLMs. How the Fingerprinting Leaderboard works, SaTML 2026 findings, and how it differs from SynthID.
Comparisons · 10 min readListen
Pangram vs Turnitin: Which Should You Use?
Pangram vs Turnitin in 2026: freemium plus LMS vs campus only AI detection, what the Springer study found, and which tool fits schools, teachers, and students.
· updated
Best of · 8 min readListen
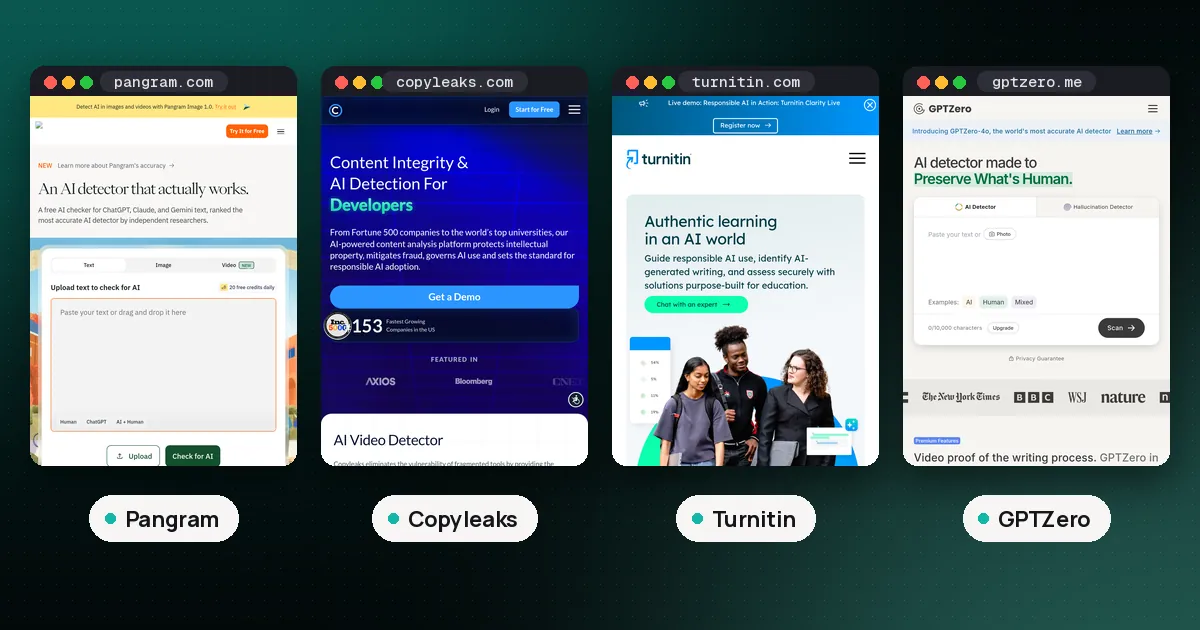
Best Free AI Detector in 2026: Top Picks
Best free AI detector in 2026: Pangram, GPTZero, ZeroGPT and Originality.ai free limits, who each fits, and how to use scores without false accusations.
· updated
Explainers · 10 min readListen
AI Agent Observability: What It Is and Top Tools
AI agent observability explained: trace tool loops, permissions and memory, the six PAI telemetry gaps, and which tools fit, from Langfuse to Datadog.
· updated
Comparisons · 7 min readListen
OpenAI Evals vs DeepEval: Which to Use?
OpenAI Evals vs DeepEval in 2026: platform shutdown timeline, DeepEval's pytest CI metrics, multiprovider support, and Promptfoo as the migration path.
· updated
Comparisons · 10 min readListen
Originality.ai vs Turnitin: Accuracy, Use Case, Buyer
Originality.ai vs Turnitin in 2026: which detector is more accurate in peer reviewed studies, how their AI scores differ, and which buyer each one fits best.
· updated
Explainers · 9 min readListen
SWE-Bench Pro Explained: V1, V2, Scores
SWE-Bench Pro explained: how Scale AI's coding benchmark differs from Verified, what V2 changed, and the November 2026 full, HARD-51 and private scores.
· updated
How to · 7 min readListen
How to Use Originality.ai for Free
How to use Originality.ai for free in 2026: 100 free credits per account (about 10,000 words), how credits burn by model, privacy notes and how to read AI scores.
· updated
How to · 8 min readListen
How to Use Pangram on Substack
How to use Pangram on Substack: Scan for AI text on web and iOS, creator controls, July 2026 limits, and how to read the human vs AI assisted estimate.
· updated
Comparisons · 10 min readListen
Pangram vs GPTZero: Which Should You Use?
Pangram vs GPTZero in 2026: free plans, Pangram 4 and GPTZero 4o, what independent studies found, and which AI detector fits educators, publishers, and teams.
· updated
How to · 8 min readListen
SynthID Detector: How to Check for AI Watermarks
Google's SynthID Detector is now open to everyone. How to check images, video and audio for its AI watermark, what results mean, the limits, and alternatives.
· updated
Explainers · 10 min readListen
HLE Diamond Leaderboard and Scores (November 2026)
HLE Diamond leaderboard for November 2026: Claude Fable 5.2 leads both official tables, 72.4% on Scale's 21 model board and 74.3% in the authors' table.
· updated
Comparisons · 10 min readListen
LLM Leaderboards Compared: Which Ones to Trust
Every major LLM leaderboard compared: how Arena, Artificial Analysis, LiveBench, SEAL, Epoch AI and Vellum score models, and where each one can mislead you.
· updated
Best of · 10 min readListen
Best LLM Observability Tools in 2026, Compared
The best LLM observability tools in 2026 compared: Langfuse, LangSmith, Phoenix, Opik, Weave and more, with licenses, self hosting and who now owns what.
· updated
Best of · 7 min readListen
Best LLM Evaluation Frameworks in 2026, Compared
The best LLM evaluation frameworks in 2026: Promptfoo, DeepEval, Ragas, Inspect and TruLens for apps, plus lm-evaluation-harness and HELM for model benchmarks.
· updated
Comparisons · 9 min readListen
Langfuse vs LangSmith: Which Should You Use?
Langfuse vs LangSmith in 2026: open source license, self hosting, pricing, retention, framework fit and migration tips, so you can pick the right LLM tracer.
· updated
Explainers · 10 min readListen
Deepfake Detection: Hive, SynthID and C2PA Compared
Deepfake detection in 2026: how Hive's deepfake detector, SynthID watermarks and C2PA Content Credentials work, how accurate they are, and a checklist.
· updated
Explainers · 6 min readListen
LLM Hallucination Detection: Methods and Tools
How LLM hallucination detection works in 2026: faithfulness checks, detector models like HHEM, self consistency and semantic entropy, and the tools to use.
· updated
Explainers · 8 min readListen
LLM as a Judge: How It Works and When to Trust It
LLM as a judge explained: how model graders work, the biases that skew them, how to validate one against human labels, and which tools to use.
· updated
How to · 9 min readListen
How to Evaluate LLM Applications (2026 Guide)
How to evaluate LLM applications step by step: error analysis, code checks, calibrated LLM judges, CI gates and production sampling, with tools for each stage.
· updated
Comparisons · 8 min readListen
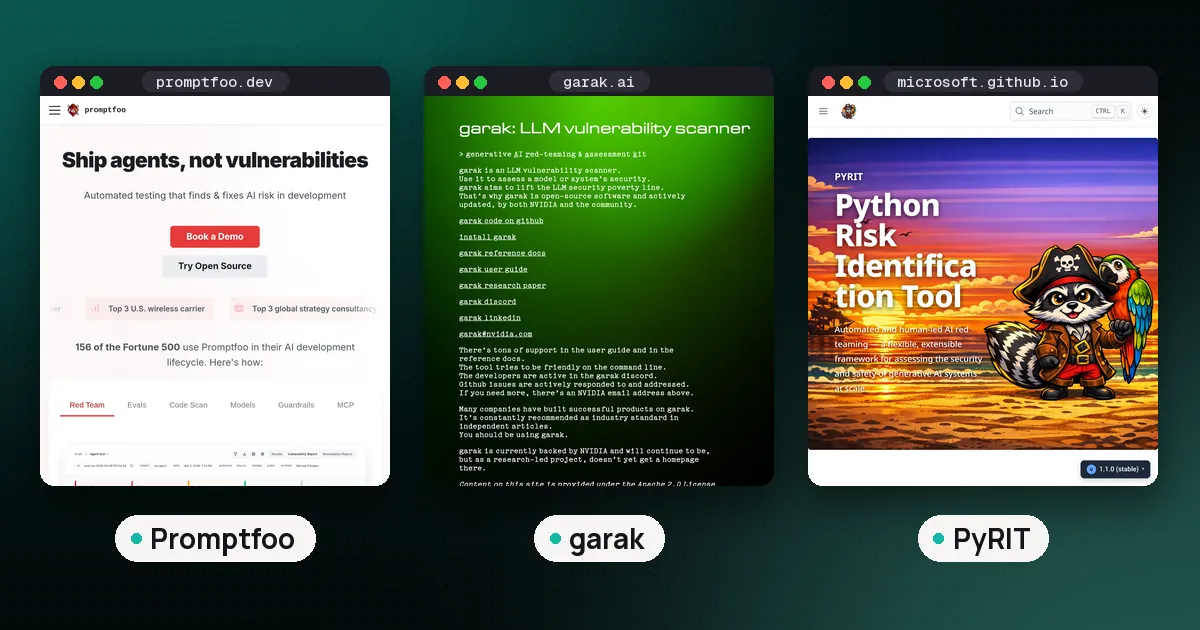
LLM Red Teaming Tools: Promptfoo, garak, PyRIT
The best LLM red teaming tools in 2026 compared: Promptfoo, garak, PyRIT, DeepTeam and Giskard, with licenses, first commands and OWASP LLM Top 10 coverage.
· updated
Comparisons · 7 min readListen
Langfuse vs Arize Phoenix: Which to Self Host?
Langfuse vs Arize Phoenix in 2026: licenses, self hosting stacks, features, managed pricing, new owners and which open LLM tracing tool fits your team best.
· updated
Explainers · 9 min readListen
Are AI Detectors Accurate? What 2026 Studies Show
Are AI detectors accurate? What 2026 studies found on Turnitin, GPTZero, Originality.ai and Pangram, false positives, edited text, and what to do if flagged.
· updated
Explainers · 10 min readListen
LLM Benchmarks Explained: What the Scores Mean
LLM benchmarks explained: what MMLU, GPQA Diamond, Humanity's Last Exam, SWE-bench and ARC-AGI measure, why scores saturate, and how to spot contamination.
· updated
Explainers · 8 min readListen
Prompt Injection Attacks: Examples and How to Test
What a prompt injection attack is, direct and indirect examples, why there is no complete fix, and how to test your LLM app with Promptfoo, garak and PyRIT.
· updated
Explainers · 7 min readListen
RAG Evaluation Metrics: Ragas vs DeepEval vs TruLens
RAG evaluation metrics explained: faithfulness, relevancy, context precision and recall, which need a reference, and how Ragas, DeepEval and TruLens differ.
· updated
Comparisons · 10 min readListen
GPTZero vs Turnitin: Which AI Detector Is Better?
GPTZero vs Turnitin in 2026: who can use each, what scores mean, what independent studies found, GPTZero 4o and Turnitin's 2026 model updates, and which fits.
· updated
Explainers · 7 min readListen
LLM Evaluation Metrics: What to Measure and How
The LLM evaluation metrics that matter in 2026: exact match, BLEU, ROUGE, BERTScore, pass@k, LLM judge rubrics, RAG and safety metrics, and when to use each.